Pipeline Parallelism
Cluster 1 tests the hypothesis that pipeline parallelism can unlock meaningful inference performance from commodity GPU hardware.
By distributing model layers across lower-cost GPUs in sequence, the cluster explores whether intelligent software architecture can substitute for raw hardware capability and offer a compelling alternative to the latest and most expensive silicon.
Future clusters will comprise leading edge and experimental hardware.
Cluster specification
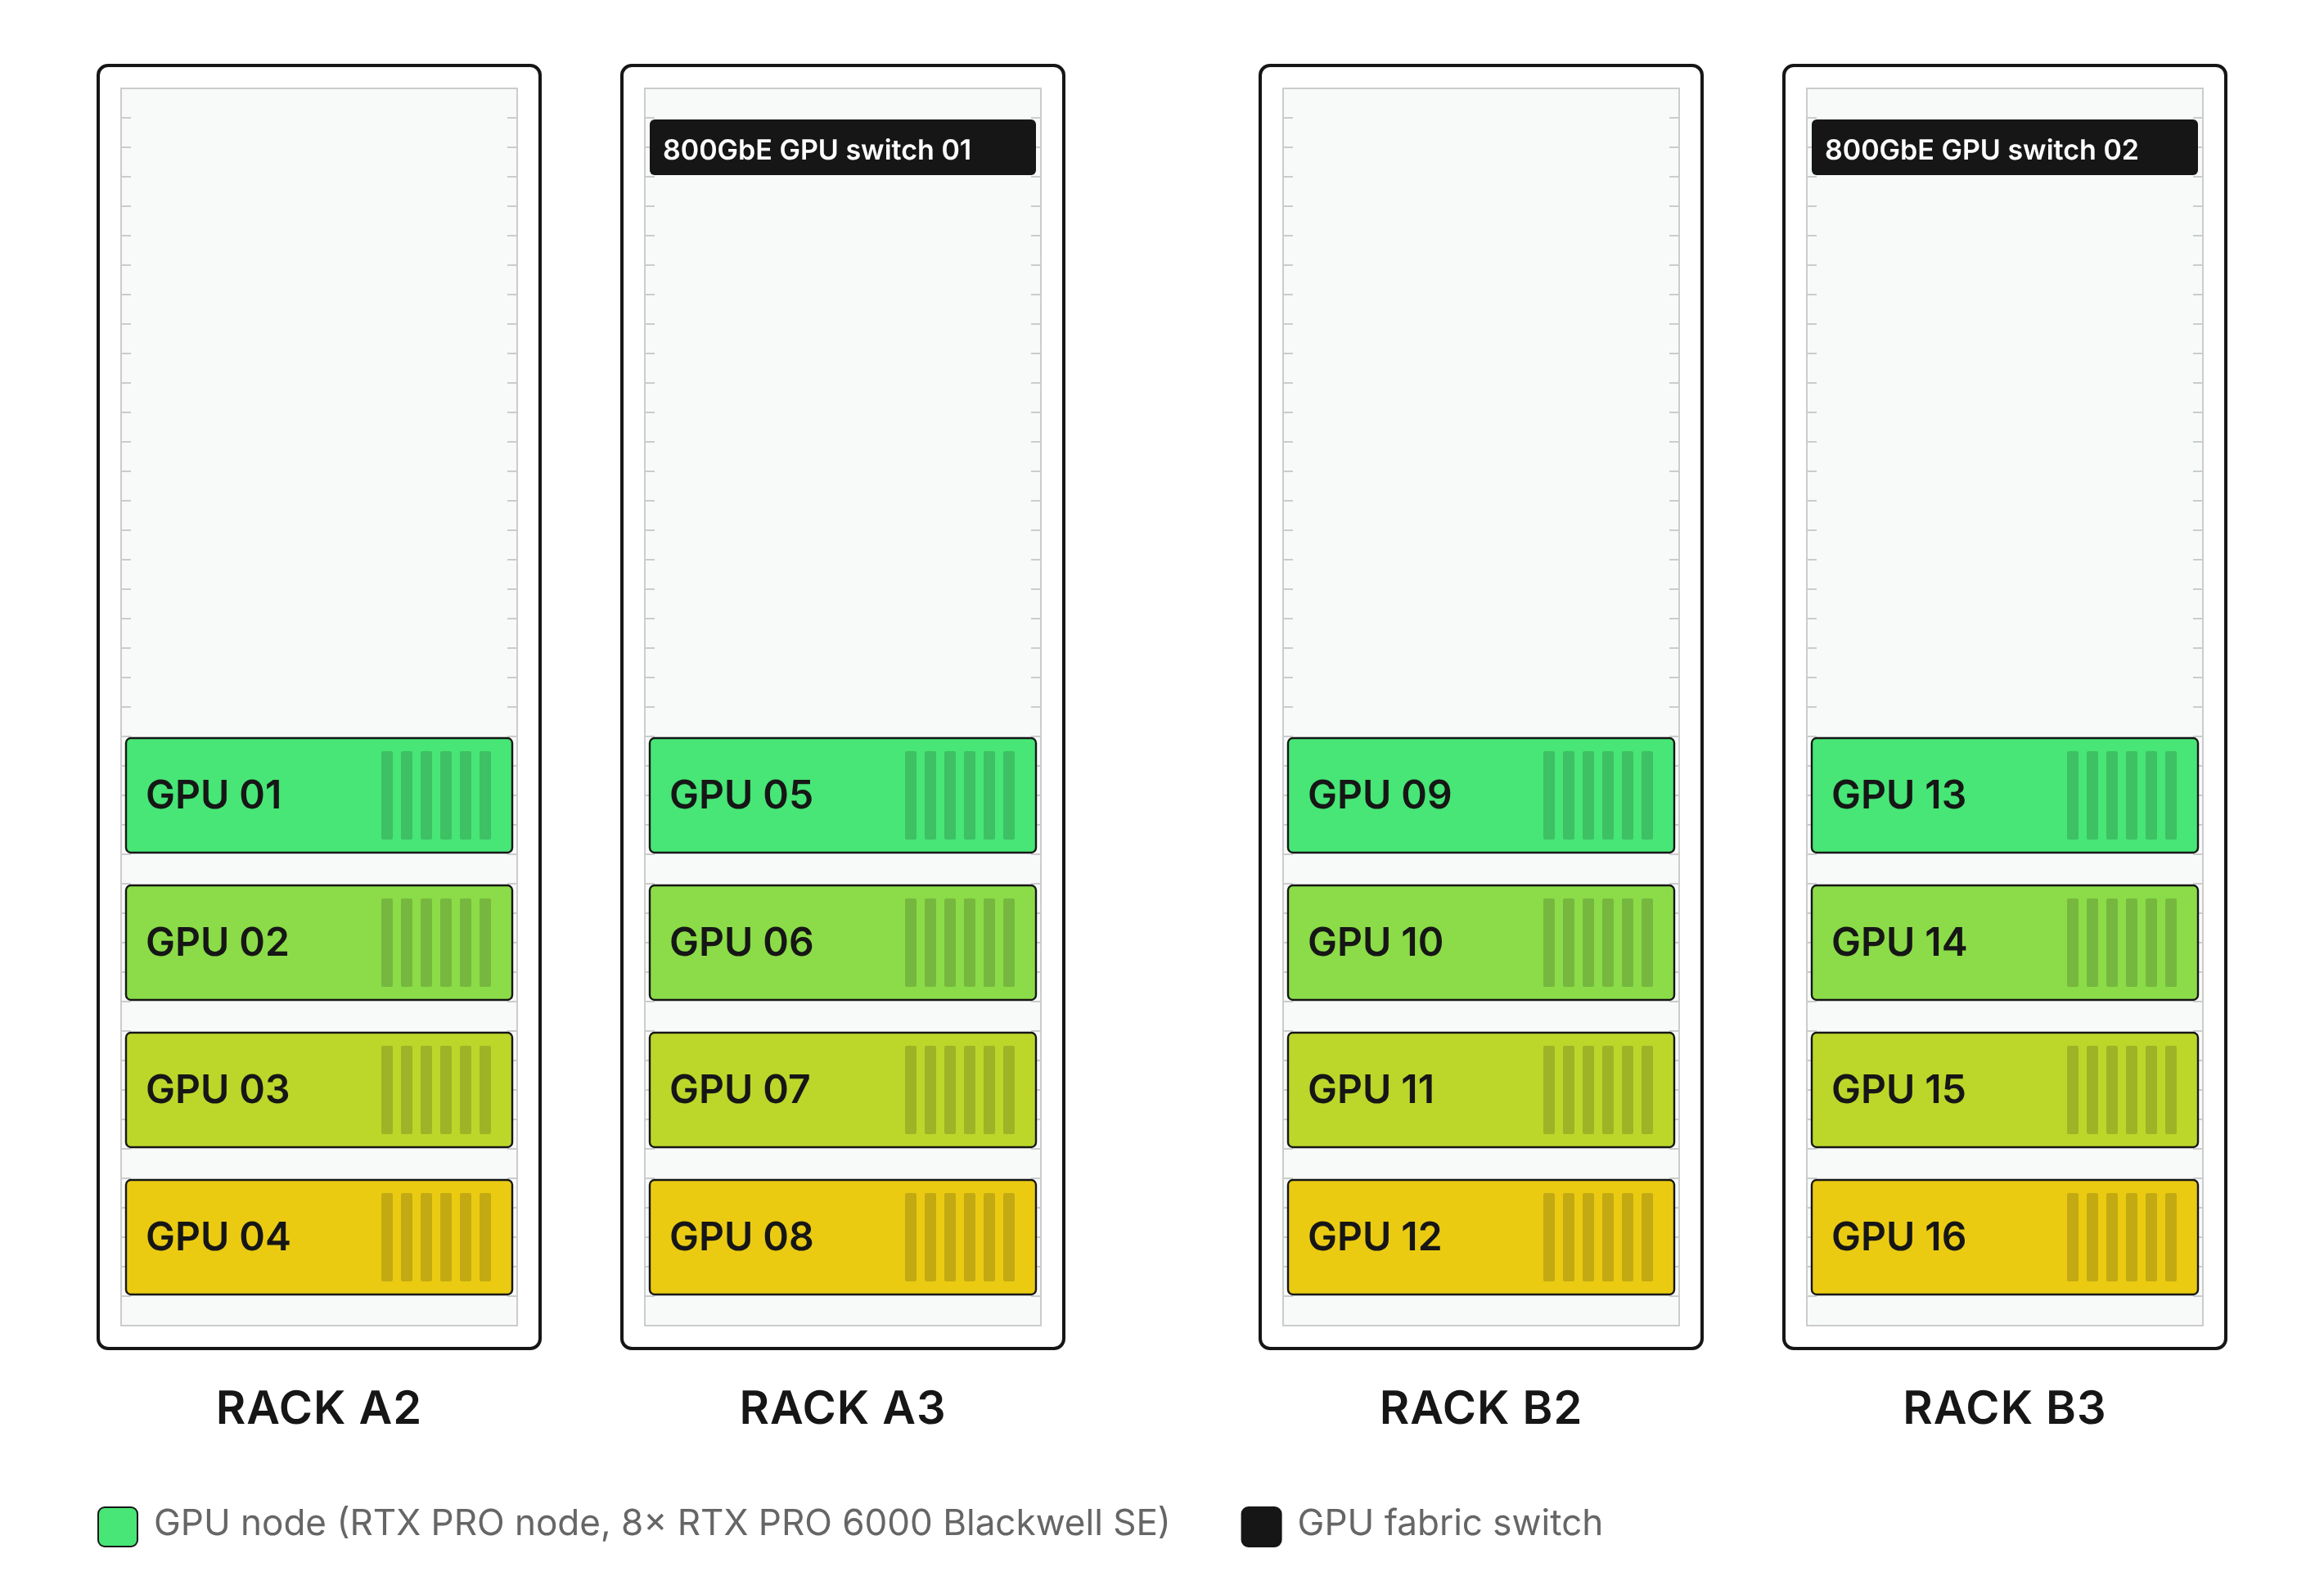
Live · Racks A2–A3, B2–B3
128
GPUs
12 TB
GPU memory
2,048
CPU cores
24 TB
System memory
Node type
RTX PRO node
Quantity
16
Server
MSI CG481-S6053
Per node
8× RTX PRO 6000 Blackwell SE 96GB · 2× EPYC 9555 64C · 1.5TB
Network
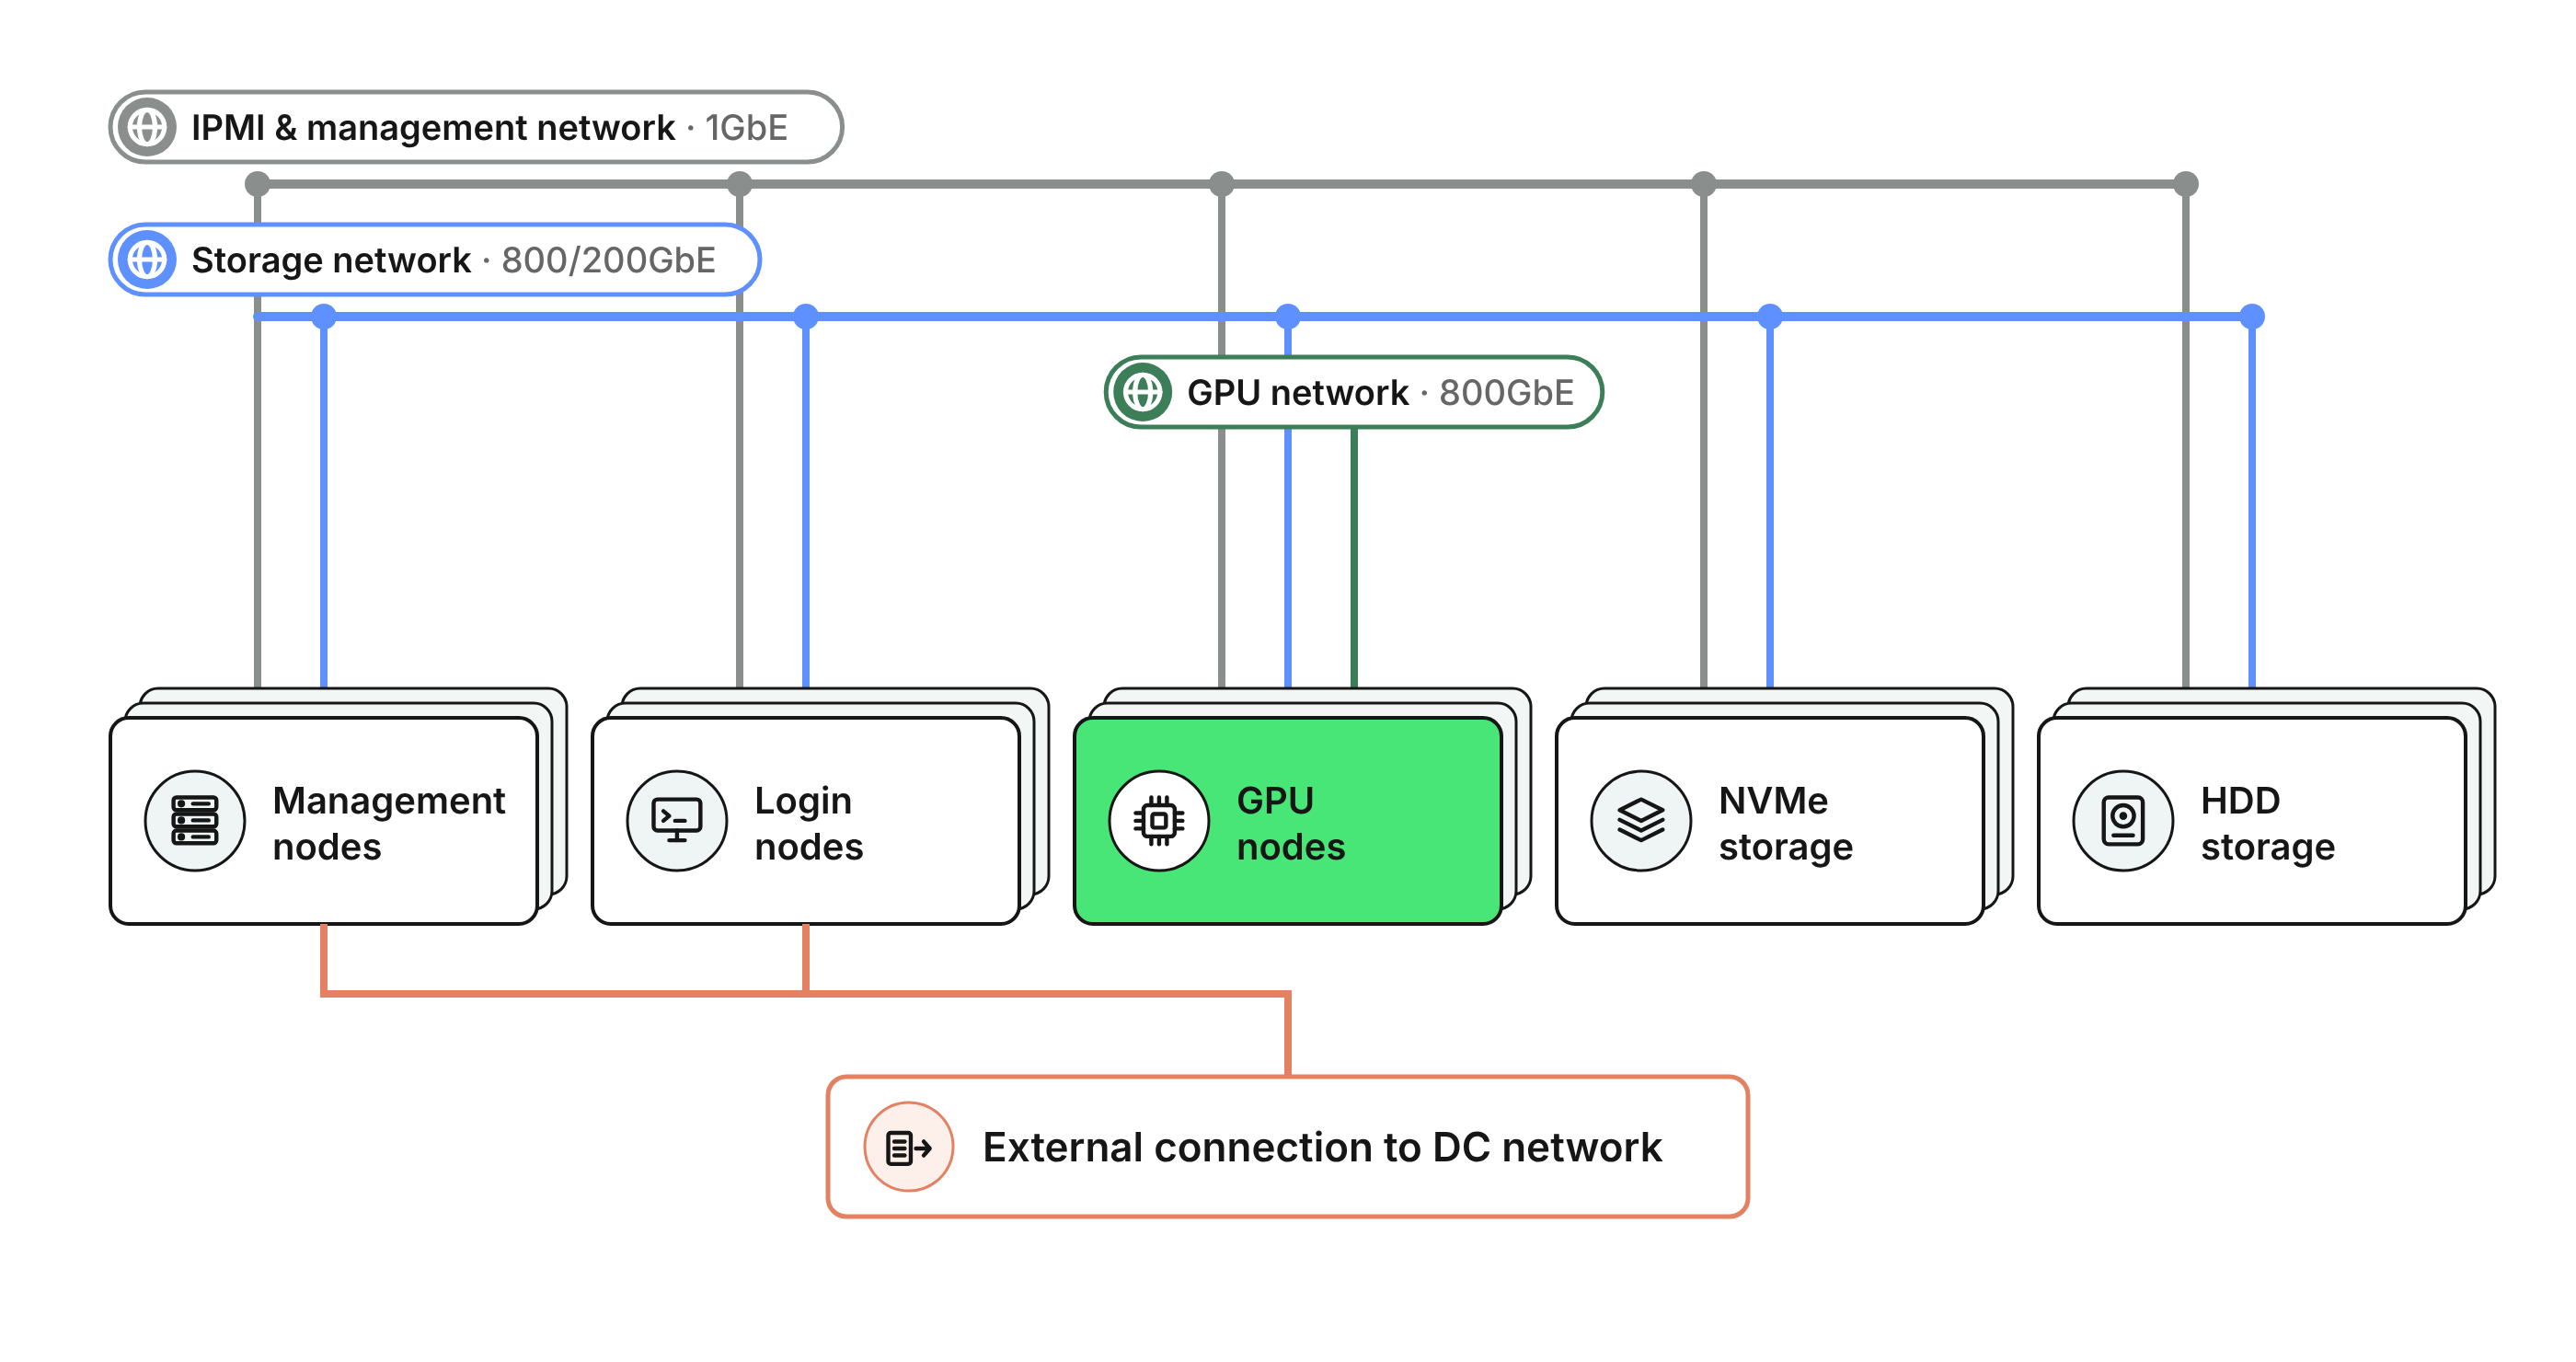
Fabric: 8× 400G ConnectX-8 · BlueField-3 2× 200GbE
Two-switch GPU↔GPU fabric (2× NVIDIA SN5610, racks A3/B3), isolated from frontend and storage traffic.
Rack layout
Network topology